xAI Grok API pricing in 2026 makes more sense when you price the whole request, not just the base token row. This page is for a developer pricing a build, and it focuses on the parts of the bill that actually move spend: long-context pricing once prompts get very large, cached input on repeated context, server-side tool calls billed per invocation, and batch or priority modes that change the rate. I checked rates against docs.x.ai on 2026-09-14.
Thin grok api pricing pages usually stop at input and output tokens. The useful view is wider: grok api cost changes with model choice, context length, caching behavior, and tool usage inside the same workflow, so two requests with similar token counts can land at very different api pricing totals.
For a quick xAI Grok pricing estimate, check AI token costs instantly.
Grok API Text Model Rates at a Glance
Grok 4.6 is xAI’s flagship text model at $2.00 input and $6.00 output per 1M tokens, while Grok Build 0.1 is the cheapest active text model at $1.00 input and $2.00 output per 1M tokens.
| Model | Context window | Input (per 1M) | Cached input | Output | Long-context tier |
|---|---|---|---|---|---|
| grok-4.6 | 500K | $2.00 | $0.50 | $6.00 | ≥200K ctx: $4.00 input, $1.00 cached, $12.00 output |
| grok-build-0.1 | 256K | $1.00 | $0.20 | $2.00 | ≥200K ctx: $2.00 input, $0.40 cached, $4.00 output |
| grok-4.5 | 500K | $2.00 | $0.30 | $6.00 | ≥200K ctx: $4.00 input, $0.60 cached, $12.00 output |
| grok-4.3 | 1M | $1.25 | $0.20 | $2.50 | ≥200K ctx: $2.50 input, $0.40 cached, $5.00 output |
| grok-4.20-0309-reasoning | 1M | $1.25 | $0.20 | $2.50 | Standard tier shown |
| grok-4.20-0309-non-reasoning | 1M | $1.25 | $0.20 | $2.50 | Standard tier shown |
| grok-4.20-multi-agent-0309 | 1M | $1.25 | $0.20 | $2.50 | Standard tier shown |
Checked against xAI pricing documentation snapshot dated 2026-08-21.
The 200K Long-Context Cliff
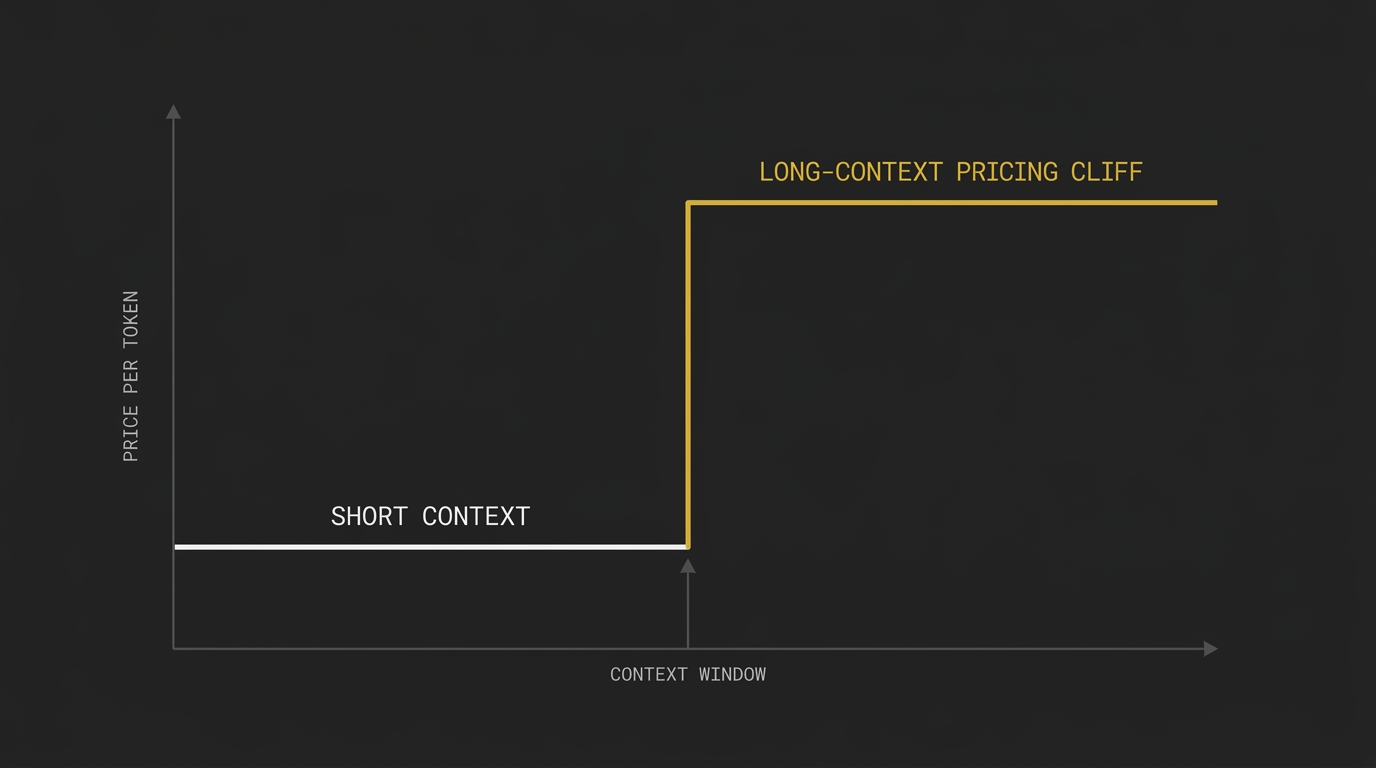
The 200K-token threshold can double your request cost in one step, because a long-context model rebills the whole request at the higher tier once the prompt reaches that line. That is why a spreadsheet built from one base rate often misses the real invoice when a workload sits near 200K context.
Long-context threshold
At this prompt size, the request moves into the higher context tier on Grok 4.6.
Input rate per 1M tokens
Grok 4.6 input pricing doubles once the prompt reaches long context.
Output rate per 1M tokens
The same request also uses the higher output tier after the threshold is crossed.
How the threshold rebills the whole request
On Grok 4.6, a prompt below 200K tokens uses the short-context rates, and a prompt at 200K tokens or more uses the long context rates for the full request. In plain English, the jump applies to all billed input, cached input, and output in that request.
That billing shape creates a real cliff. A job that usually lands at 195K to 199K prompt tokens can price one way all week, then jump hard when one request lands at 201K.
For more background on what affects token cost, context tiering is one of the biggest line items to watch.
A worked example: just under versus just over
Take the same Grok 4.6 job with 50,000 output tokens, then change only the prompt size. At 199,000 prompt tokens, the request stays on the short-context tier: input cost is 199,000 / 1,000,000 × $2.00 = $0.398, output cost is 50,000 / 1,000,000 × $6.00 = $0.30, for a total cost of $0.698.
Now push that same prompt to 201,000 tokens. The whole request moves to long context: input cost is 201,000 / 1,000,000 × $4.00 = $0.804, output cost is 50,000 / 1,000,000 × $12.00 = $0.60, for a total cost of $1.404.
So a 2,000-token increase in the prompt adds $0.706 to the bill in this example. That is the practical takeaway: keep individual prompts under the 200K threshold when you can.
Cached Input Changes the Bill on a Repeated System Prompt
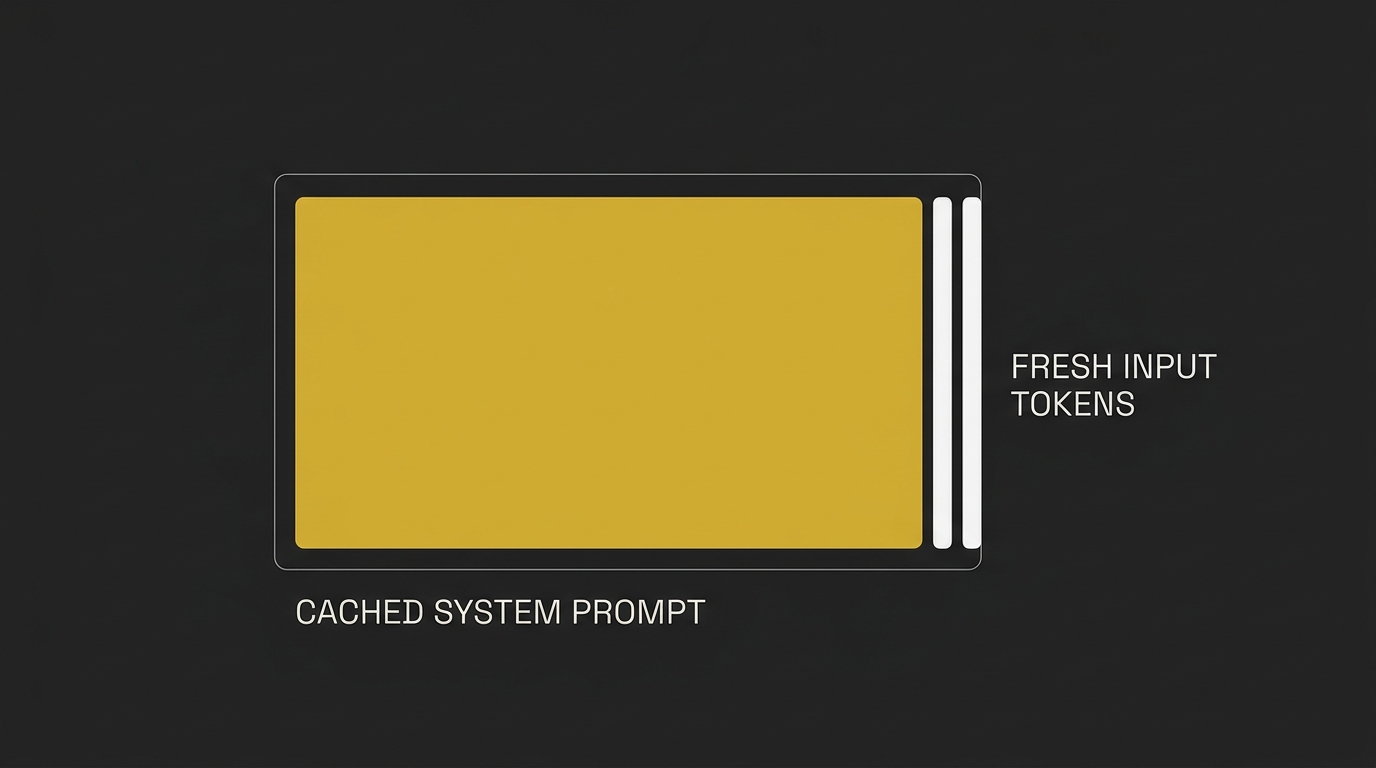
Cached input cuts the cost of reused prompt text hard, and the discount changes by model. For Grok’s flagship tier, Grok 4.6 prices cached input at $0.50 per 1M tokens, versus $2.00 per 1M fresh input tokens, so the same request lands very differently once part of the prompt is served from cache. That gap matters most when a stable system prompt, policy block, or document prefix goes out on every request.
So the useful way to price a repeated workflow is to split the prompt into reused input tokens and fresh input tokens, then apply the model’s cached-input row to the reusable part. Cached input is typically a fraction of uncached input across providers, and some models price that gap more aggressively than others, which means grok cached input pricing can change the bill a lot even when your app behavior stays the same. For a chatbot, agent, or research flow with the same opening prompt on every request, a cache hit can be several times cheaper than a cache miss.
Server-Side Tools Bill Per Invocation on Top of Tokens
xAI bills server-side tools separately from model tokens, so the same model can produce a higher bill when a request calls search, code execution, file search, or collection retrieval. That is the layer many pricing sheets miss, especially on agentic requests that trigger multiple tool calls inside one run.
| Tool | Cost | What triggers the charge |
|---|---|---|
| Web Search | $5 / 1k calls | Each web_search invocation |
| X Search | $5 / 1k calls (current basis) | Each x_search invocation under the current pricing basis |
| Code Execution | $5 / 1k calls | Each code_execution or code_interpreter invocation |
| Collections Search | $2.50 / 1k calls | Each collections_search or file_search invocation against uploaded collections |
| File Attachments | $10 / 1k calls | Each attachment_search invocation across attached files |
Web search, X search, code execution and collections search
These tools add per-invocation charges above the base token line. So if two requests use the same Grok model, the one that searches the web, queries X, runs Python, or hits a collection can cost more even when the token count looks similar.
That matters most on autonomous or multi-step requests, because the model can trigger several tool calls in one run. If you want a closer forecast, count both layers: tokens for the model and tool calls for the workflow. For a practical next step, a token estimator helps size the token side before you add the tool layer.
The X Search billing change effective September 21, 2026
X Search shifts to result-based billing on September 21, 2026 at 12:00 PM PT. The current basis is $5 per 1k calls, and the announced basis is $5 per 1k posts fetched plus $10 per 1k user profiles fetched.
The trigger also changes with that update. Every post returned by a search or thread fetch counts toward the posts-fetched charge, including parent and quoted posts, and every profile returned by a user search counts toward the profiles-fetched charge.
Batch and Priority Processing Move the Rate
Batch processing lowers the token rate for asynchronous jobs, and the discount is model-specific. xAI currently publishes a 20% batch discount for grok-4.3, grok-4.20-0309-reasoning, grok-4.20-0309-non-reasoning, and grok-4.20-multi-agent-0309, with most batch jobs completing within 24 hours. That batch discount applies across input, output, cached, and reasoning tokens, while image and video batch usage stays at standard rates.
Priority Processing moves the rate the other direction: eligible text requests that are served at the priority tier bill at 2x standard token rates. The 2x multiplier applies to input, output, cached, and reasoning tokens, and cached-prompt discounts are applied before the multiplier. So these are two clean workload levers: batch for background requests where turnaround can sit in a queue, priority for chat or response requests where lower latency is worth the premium.
How Grok Compares to Other Providers on the Same Workload
Grok 4.6 sits in the middle of the current frontier pack on base token price: $2.00 input and $6.00 output per 1M tokens, versus GPT-5.6 Sol at $5.00 input and $30.00 output, Claude Opus 5 at $5.00 input and $25.00 output, and Gemini 3.7 Flash at $0.75 input and $3.75 output. Across these models, the spread is wide enough that price alone can swing the bill hard, especially once output tokens start climbing in longer generations.
But raw model rates still don’t settle the real cost of an xai api build, because the same workload can land very differently by prompt shape, cacheability, tool calls, and how much text the model sends back.
Estimate Your Grok Bill Before You Build
Cost estimation belongs before the build, because Grok pricing can change fast when a request crosses the 200K-token line, pulls in cached input, or shifts model tier. My free, independent AI Token Calculator runs in the browser and carries Grok’s long-context tiers, so you can price the same request under and over that threshold without doing the arithmetic by hand, then keep usage aligned with the budget you actually want.
Frequently Asked Questions
Is the Grok xAI API free?
The Grok xAI API is usage-based and billed per token. xAI supports prepaid credits or monthly invoiced billing, and the Console Playground is available for testing before you add billing.
How much does the Grok xAI API cost per million tokens?
Grok 4.6 currently costs $2.00 per 1M input tokens, $0.50 per 1M cached input tokens, and $6.00 per 1M output tokens. Grok Build 0.1 is the cheapest active text rate in the provided pricing set at $1.00 per 1M input tokens and $2.00 per 1M output tokens.
What triggers Grok’s long-context pricing?
Grok’s long-context pricing starts when the prompt reaches 200K tokens. At that point, the whole request is rebilled at the higher long-context rate for that model.
Do server-side tools cost extra on top of tokens?
Server-side tools bill separately per invocation on top of model tokens. That means a request that calls web search, X search, code execution, file search, or collections search can carry tool charges alongside token cost.
How is API pricing different from a SuperGrok subscription?
API pricing is separate from any SuperGrok consumer subscription and runs on its own usage meter. Subscription quota labels also don’t map cleanly to API billing, because API charges are based on metered tokens and tool usage, while subscription limits can follow separate counters and account bars.